Engines and integrations
Bring your own engine.Keep your own stack.
Brunelly runs the leading coding engines and models, on your accounts if you prefer, and works inside the repositories and trackers your teams already use. Model choice stays yours as prices and capabilities change.
What Brunelly works with
Engines, models, repositories and trackers.
- Coding engines
- Claude Code
- OpenAI Codex
- Gemini
- Qwen
- Kimi
- Model vendors
- Anthropic
- OpenAI
- DeepSeek
- Zhipu GLM
- Alibaba Qwen
- Moonshot Kimi
- Your own model accounts
- Your own API keys
- Claude on Azure AI Foundry
- Claude on AWS Bedrock
- Claude on Google Vertex AI
- OpenAI- and Anthropic-compatible endpoints
- Repositories
- GitHub
- Azure DevOps
- Bitbucket
- Brunelly-hosted Git
- Work tracking
- Jira
- Azure Boards
- Brunelly boards and backlogs
Mix and match
A different model for every job.
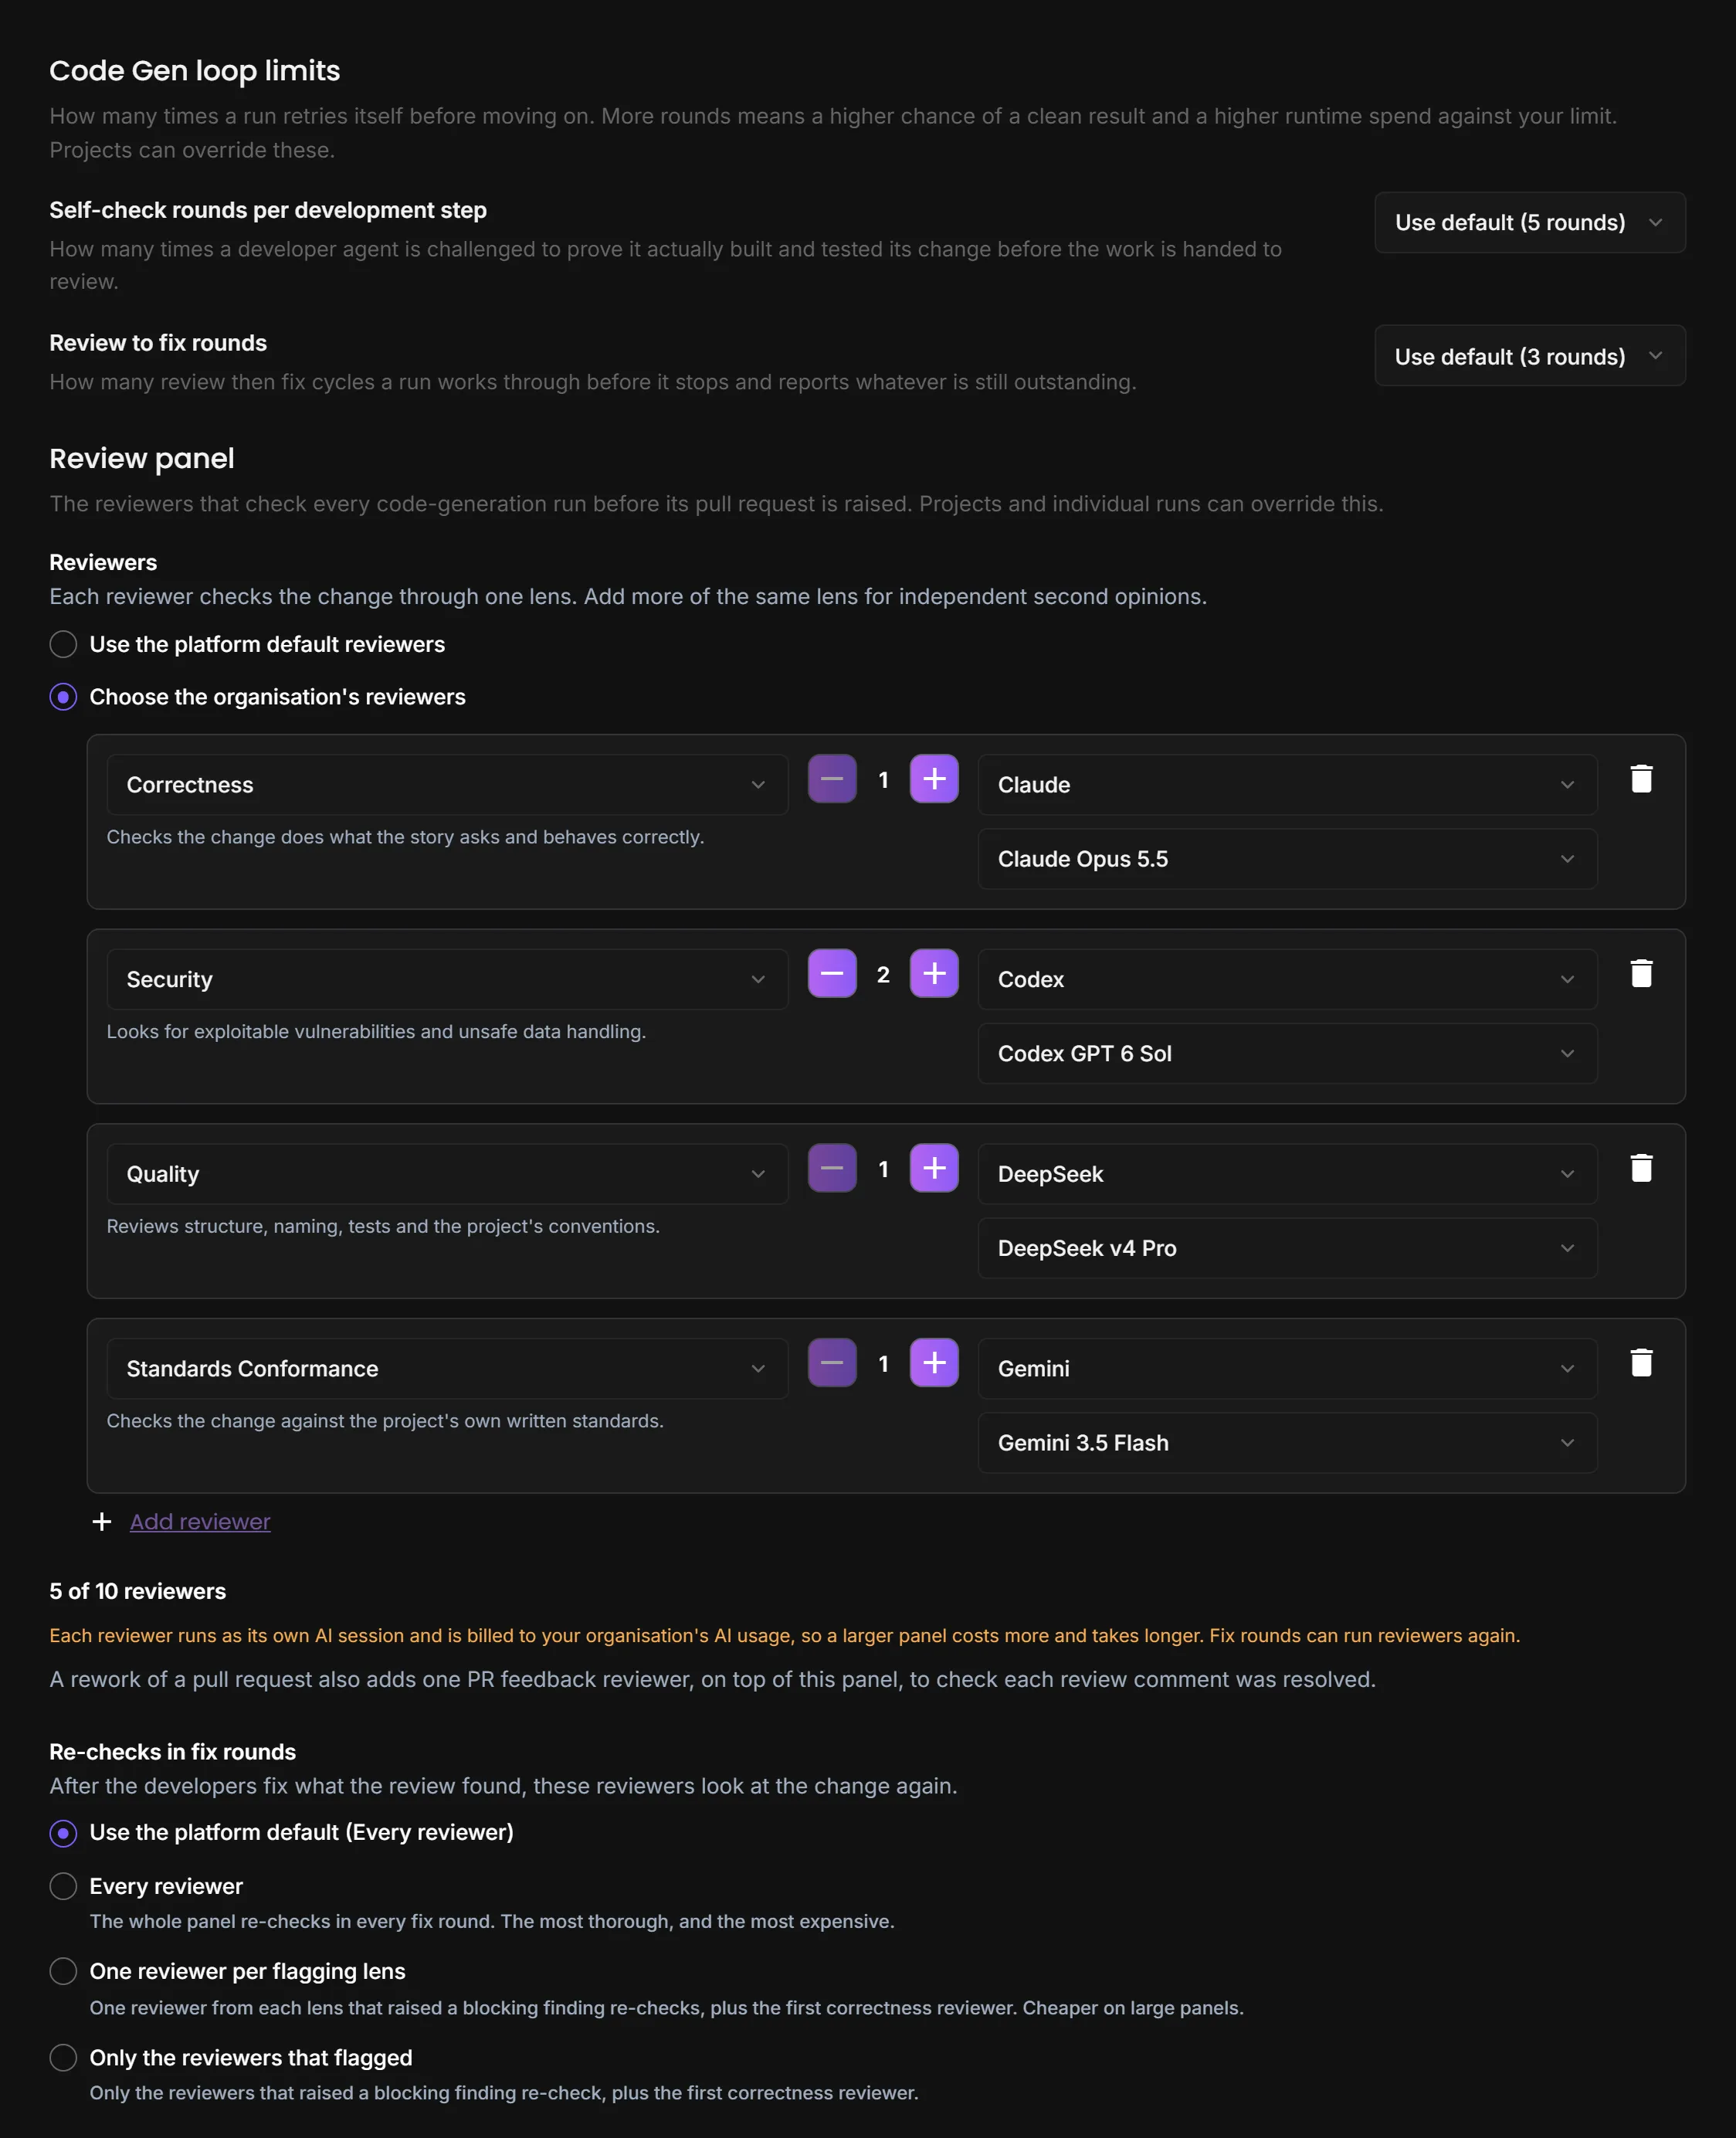
Give each architect and each reviewer its own engine and model. A blind spot in one vendor's model is caught by another's, which is how the PaymentGuard leak was found.
- Engine and model per architect and per reviewer
- Your own API keys, or Claude through your own cloud account
- Change models as prices and capabilities move
Keep exploring
The rest of the platform.
How it works
The governed engineering process, step by step
Review panel
Blind review across models, decided by rule
Code Assurance
Six lenses on any code, including code you did not write
Planning and context
Boards, stories and what Brunelly knows about your code
Governance
Your standards enforced at merge, with exceptions on the record
Security and trust
How we protect your code, credentials and the record
Get started
Make software engineering repeatable.
Every engagement starts with a scoped pilot on one problem that matters, measured against how your team works today.